Eleven v4 vs Eleven v3 vs Seed Audio 1.0: Which AI Voice Model to Use in 2026
Oct 2026
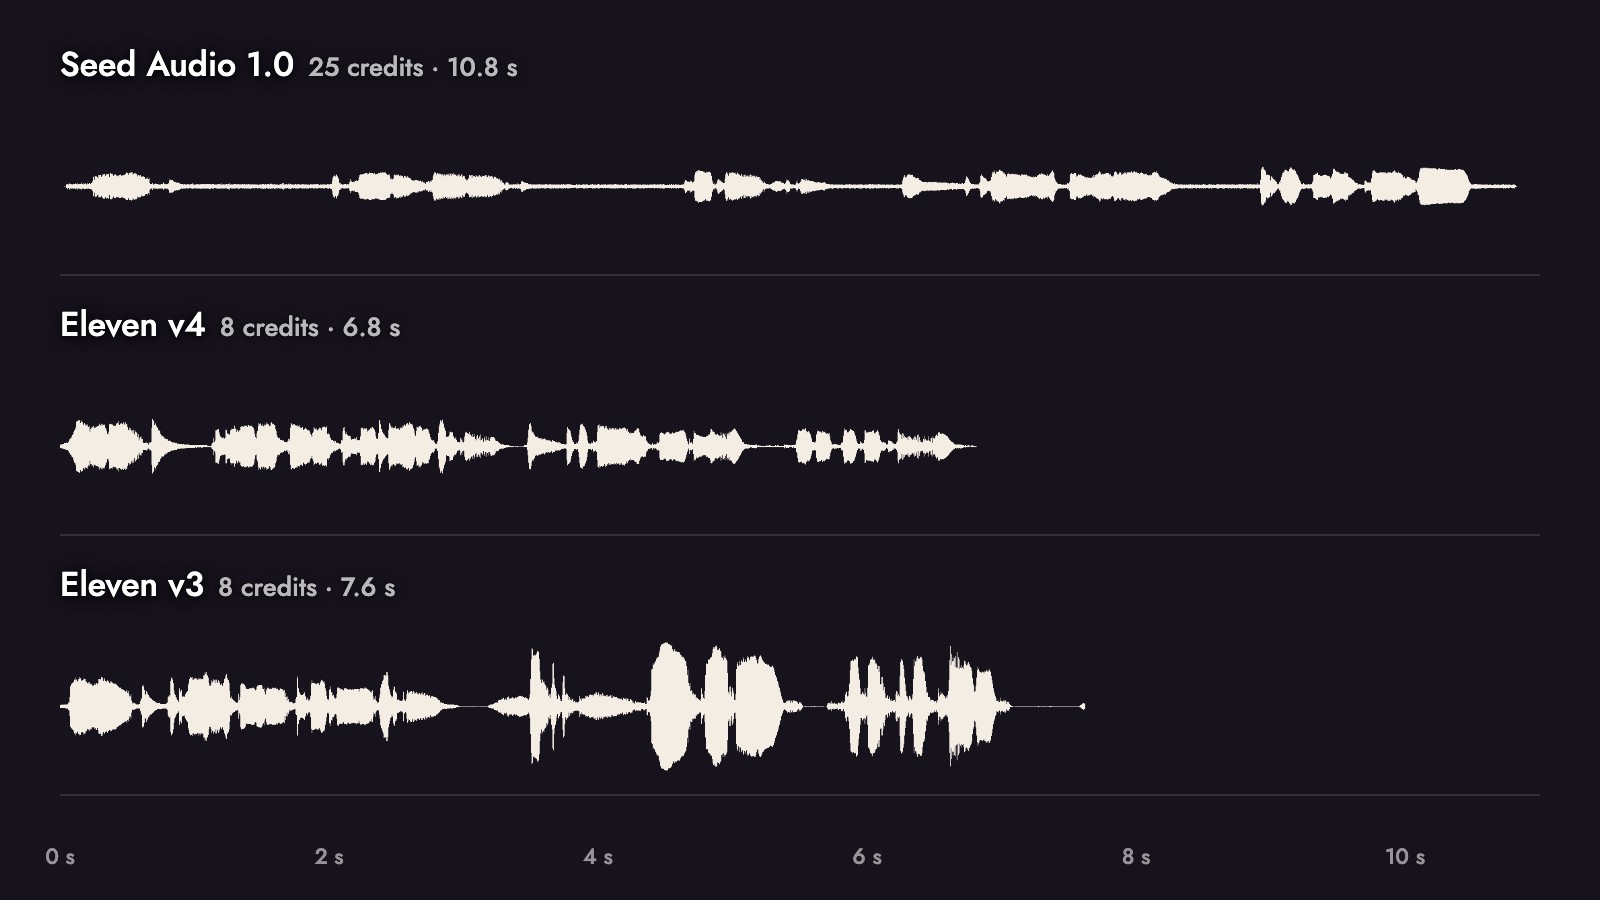
Flick's Text to Voice node runs three voice models: Eleven v4 and Eleven v3 from ElevenLabs, and Seed Audio 1.0 from ByteDance. We gave all three the same two lines of Halloween dialogue, with the same two characters, and listened.
Our ranking for emotional delivery: Seed Audio 1.0 first, Eleven v4 second, Eleven v3 third. Seed Audio also costs three times as much per take and works in a different way, so the best pick depends on what you are making.
Quick answer: which voice model should you use?
Add a Text to Voice node from the + button on the left toolbar, then:
- For the most emotional read, use Seed Audio 1.0. 25 credits. Describe each voice and the delivery in one prompt.
- For dialogue with chosen voices, use Eleven v4. 8 credits. Pick a voice per speaker and add [laughs]-style cues.
- Keep Eleven v3 for matching older clips. Same price as v4, but it came last in our test and ran much louder.
| Seed Audio 1.0 | Eleven v4 | Eleven v3 | |
|---|---|---|---|
| Maker | ByteDance (Volcano Engine) | ElevenLabs | ElevenLabs |
| Our emotion ranking | 1st | 2nd | 3rd |
| Credits per take on Flick | 25 | 8 | 8 |
| How you write it | One scene prompt, voices described in words | Speaker rows, a library voice per speaker | Speaker rows, a library voice per speaker |
| Voice references | Up to 3 audio or video clips, or 1 image | Voice library | Voice library |
| Languages (provider) | 20+ reported | 90+ | 70+ |
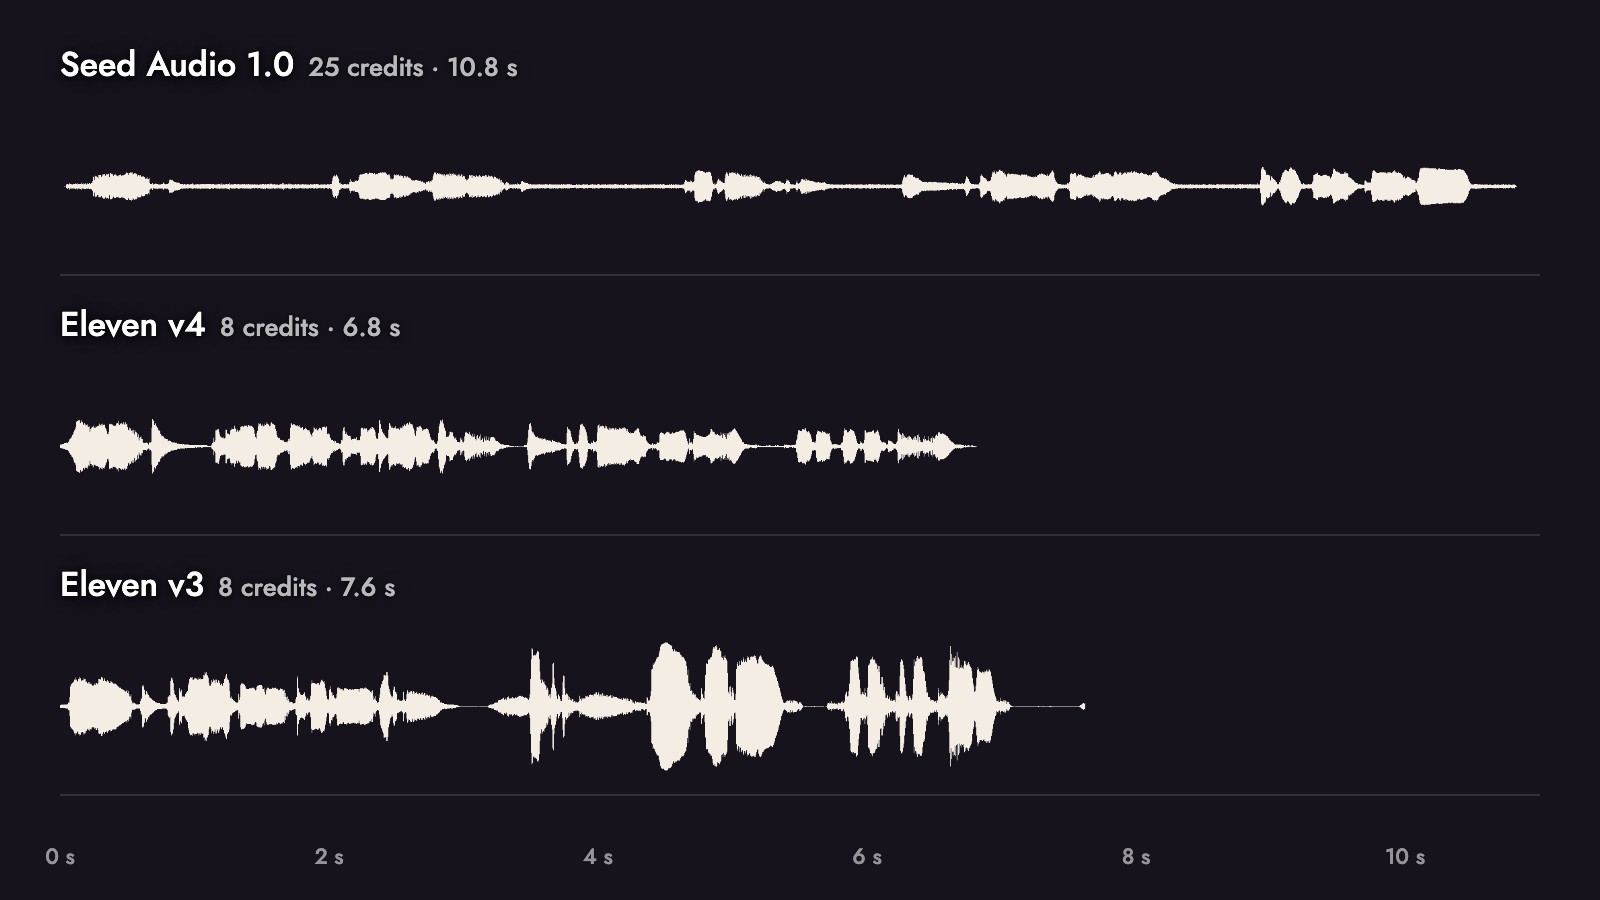
| Our take: length / time to finish | 10.8 s / 45 s | 6.8 s / 90 s | 7.6 s / 139 s |
| Output we got | MP3, 24 kHz stereo | MP3, 44.1 kHz mono | MP3, 44.1 kHz mono |
Give your characters a voice
Pick a voice per speaker, or describe the performance and let Seed Audio act it.
The test: one dialogue, three models
Two characters, two lines:
- Speaker 1, calm, with a South African accent: "You're late. The candles burned out twenty minutes ago."
- Speaker 2, playful and American: "[laughs] Then light them again. I brought the good candy."
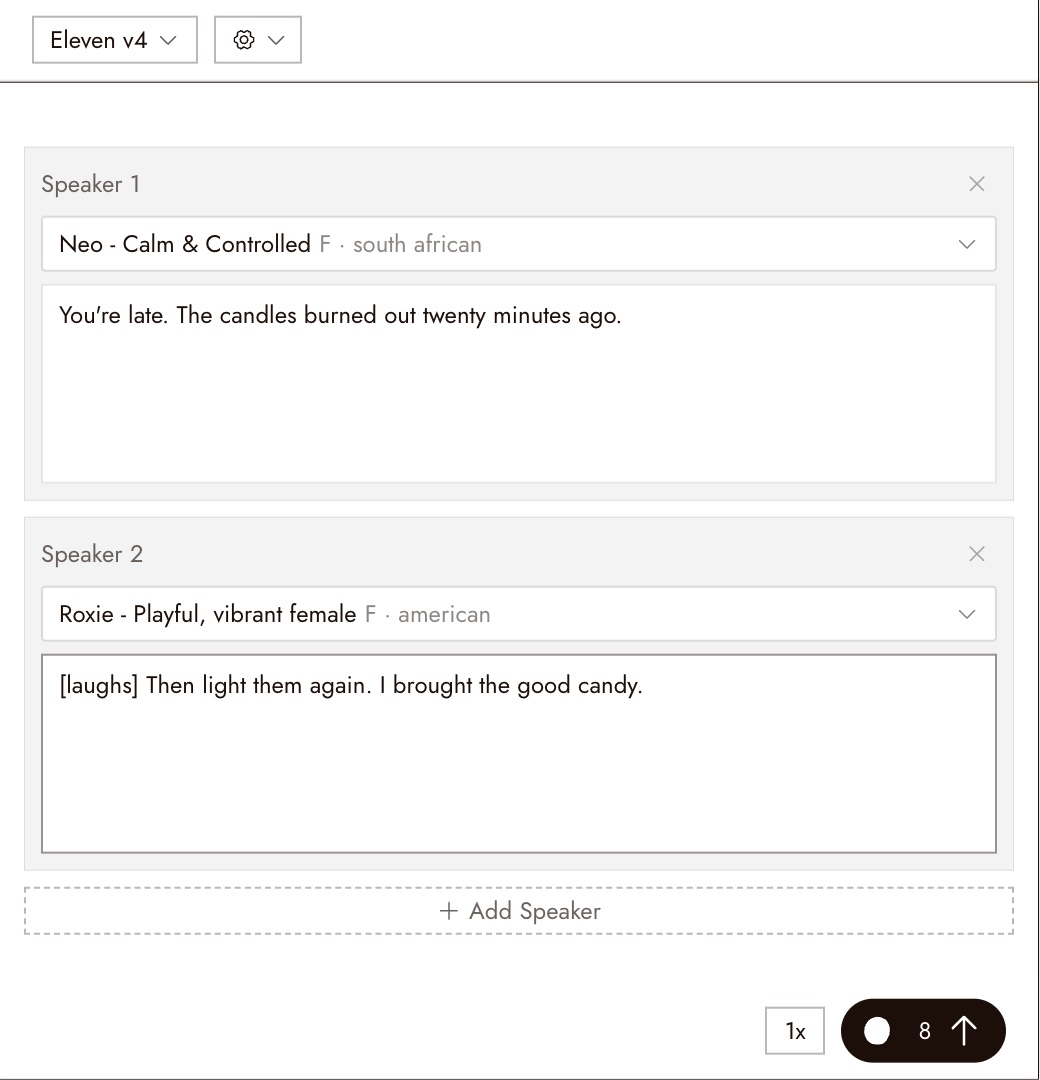
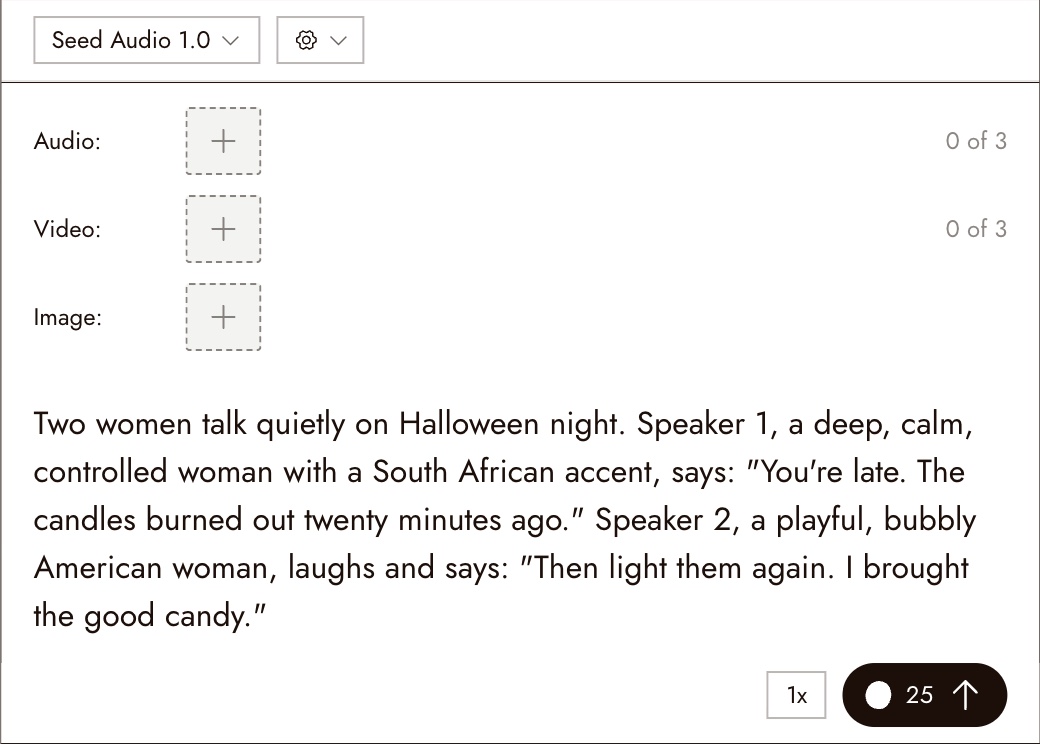
For the Eleven models we used the same two library voices, Neo (calm and controlled, South African) and Roxie (playful, American), and typed each line into its own speaker row. Seed Audio has no speaker rows, so we described the two voices in its prompt and quoted the same lines. Each model ran once, at default settings.
Seed Audio 1.0
Eleven v4
Eleven v3
What we heard
Seed Audio 1.0 had the most emotion. It also took its time: the second speaker comes in at 6.0 seconds, against 3.0 to 3.4 seconds on the Eleven models, and it left pauses of about a second inside each line. That breathing room is a large part of why it sounds acted rather than read. If you need a tight exchange, plan to trim.
Eleven v4 came second. It kept the two voices distinct, and the exchange is the tightest of the three at 6.8 seconds.
Eleven v3 came third, and it was by far the loudest. We measured integrated loudness on each file:
| Take | Loudness | Peak |
|---|---|---|
| Seed Audio 1.0 | -30.6 LUFS | -14.9 dBFS |
| Eleven v4 | -28.0 LUFS | -11.1 dBFS |
| Eleven v3 | -15.8 LUFS | -1.6 dBFS |
About 12 to 15 dB separates v3 from the other two. If you cut takes from different models into one scene, level them first.
All three read every word as written. We checked each take with a speech-to-text pass; none dropped or changed a word.
What it costs and how long it takes
Voice models on Flick charge a flat price per take, not per second.
| Model | Credits per take | Takes per month on Casual (500 credits) |
|---|---|---|
| Eleven v4 | 8 | 62 |
| Eleven v3 | 8 | 62 |
| Seed Audio 1.0 | 25 | 20 |
All three are available on every plan, including Free. Rates for every model are on model credit costs, and a failed generation is refunded (how credits work).
Time from clicking Run to a finished file, one run each: Seed Audio 45 seconds, Eleven v4 90 seconds, Eleven v3 139 seconds. One run per model is a small sample, and queue time is included.
How to set each one up
Eleven v4 and Eleven v3: speaker rows
- Click + on the left toolbar, then Generate Voice.
- Pick Eleven v4 (or v3) in the model menu.
- Under Speaker 1, click Select voice, hover a voice to preview it, and click Use.
- Type the line. Cues in square brackets such as [laughs], [whispers] or [sighs] direct the delivery.
- Click + Add Speaker for each extra voice, then check the price on the Run button and run.
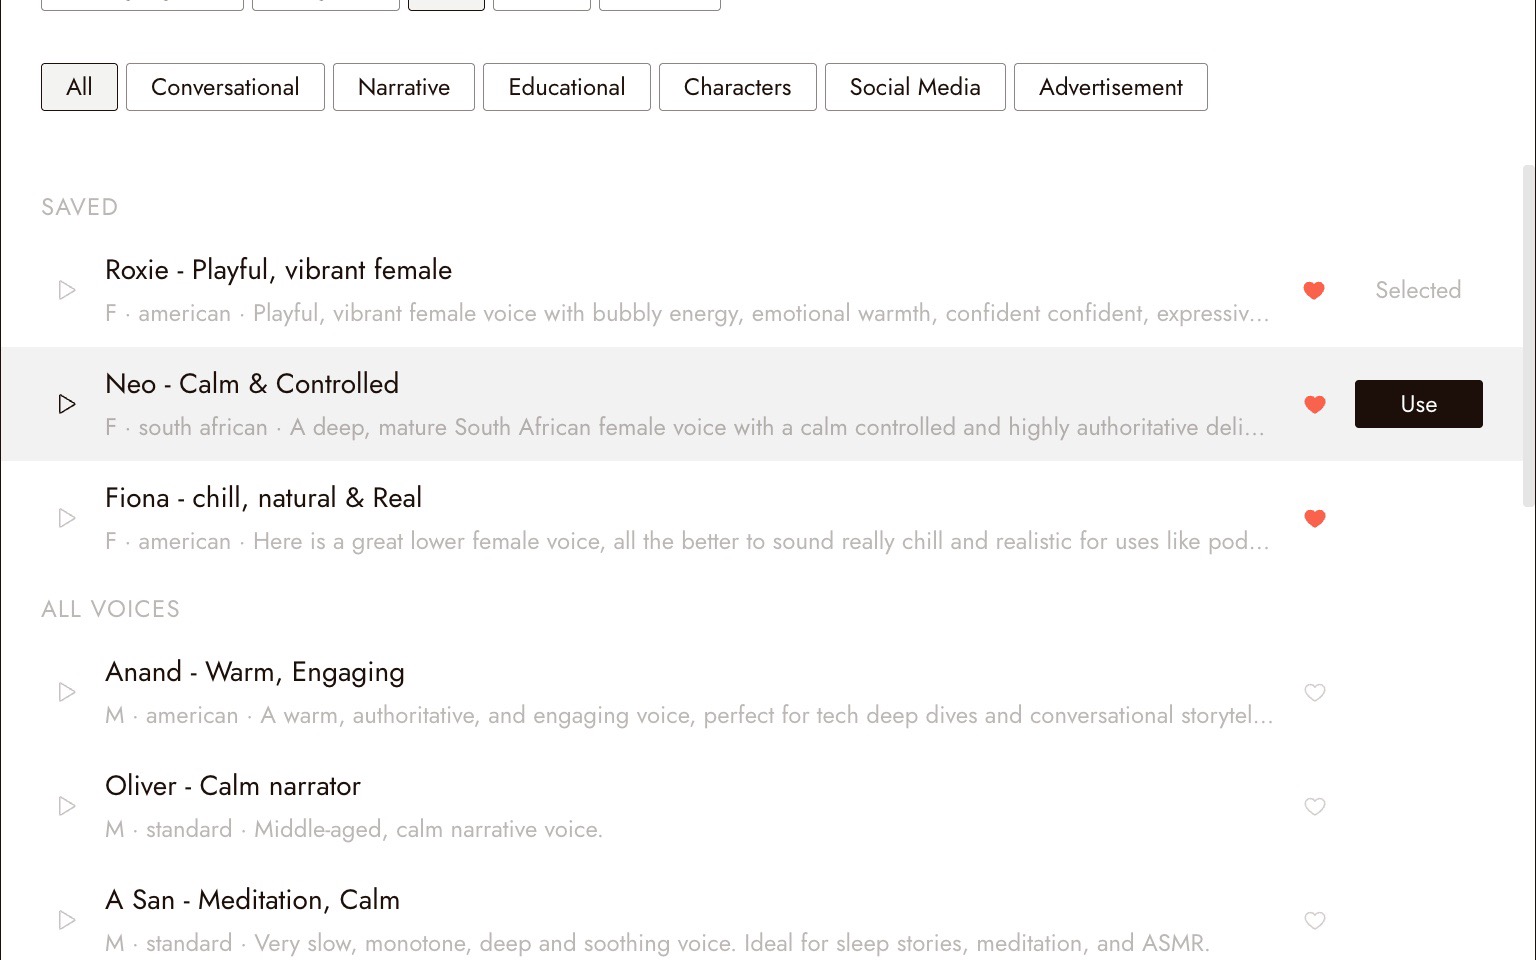
Flick allows up to 10 speakers in one take. Save the voices you reuse with the heart icon so they sit at the top of the list.
Seed Audio 1.0: one scene prompt
- In the same node, pick Seed Audio 1.0.
- Write the scene: who is speaking, how each voice sounds, the emotion, and the exact lines in quotes. The prompt holds up to 2,048 characters.
- Optionally attach up to three voice references: audio clips (30 seconds each at most) or videos with an audio track, cited in the prompt as @Audio1 or @Video1. An image reference works instead, but not together with audio or video references.
- Check the 25 on the Run button and run.
Voice for your character walks through building a character's voice in Seed Audio from a reference image.
Which one to use
| You want | Use | Why |
|---|---|---|
| The most emotional performance | Seed Audio 1.0 | Ranked first in our test |
| A voice cloned from your own recording | Seed Audio 1.0 | Takes up to 3 audio or video references |
| A tight two-hander with picked voices | Eleven v4 | Distinct voices, shortest timing |
| Many takes on a budget | Eleven v4 | 8 credits, a third of Seed Audio |
| Lines in a less common language | Eleven v4 | ElevenLabs lists 90+ languages |
| Matching clips you already made on v3 | Eleven v3 | Same voices and behaviour as before |
The column "Why" is our assessment from this test plus the providers' published specs. For a talking picture, take the finished audio into Character Dialogue.
Tips for better voice takes
- Write lines the way they are spoken. Short sentences, punctuation where you want a pause.
- On Eleven, use audio tags, not SSML. ElevenLabs says v4 and v3 do not support SSML break tags; use tags, punctuation and line breaks for timing.
- Describe voice quality when a tag could be heard as a sound. ElevenLabs suggests [low, gravelly voice] over a tag that might be played as an effect.
- On Seed Audio, describe each voice in words a casting note would use: age, pitch, accent, pace, emotion.
- Keep one voice per character across a project. Voice consistency shows how.
- Level before you cut. Our v3 take was 12 dB hotter than v4.
常见错误
- Writing a Seed Audio prompt without the exact lines in quotes. Seed Audio generates full scenes, sound included, so give it the exact words you need spoken.
- Expecting Seed Audio to keep Eleven's pace. Our Seed take ran about 60% longer than the Eleven v4 take for the same two lines.
- Mixing models in one scene without matching loudness.
- Choosing a new voice for every clip. The face can hold while the character still sounds like someone else.
Sources
- Models, ElevenLabs documentation, checked October 21, 2026
- Prompting Eleven v4, ElevenLabs documentation, checked October 21, 2026
- Introducing Eleven v4, ElevenLabs, September 28, 2026
- Seed Audio 1.0: Audio Creation Model, ByteDance Seed, July 20, 2026
- Volcano Engine releases the Doubao audio generation model 1.0, Sina Tech, June 24, 2026
- Seed Audio 1.0 API reference, fal, checked October 21, 2026
- Tests, credit prices, timings and loudness measurements from a Flick canvas, October 2026
相关指南
- Text to Voice
- Voice for your character
- Voice consistency
- Character Dialogue
- Build the sound
- Import audio
- Model credit costs
- Choosing a model
常见问题
Which is better, Eleven v4 or Seed Audio 1.0?
Is Eleven v4 better than Eleven v3? In our test, yes: more expressive, closer in loudness to other takes, and ready sooner. ElevenLabs also recommends v4 over v3 and lists 90+ languages against 70+.
Is Eleven v4 better than Eleven v3?
How much do AI voices cost on Flick? 8 credits per take on Eleven v4 or v3, and 25 on Seed Audio 1.0. The price does not change with length.
How much do AI voices cost on Flick?
Can Seed Audio clone my voice? It can match a voice from up to three reference clips of up to 30 seconds each. Use recordings you have the right to use.
Can Seed Audio clone my voice?
How many speakers can one take have? Up to 10 on the Eleven models in Flick. Seed Audio has no speaker rows: describe each speaker in the prompt.
How many speakers can one take have?
Can I use the voice in a video? Yes. Use the audio in Character Dialogue for lip sync, or attach it to a Seedance video as a voice reference.