Eleven v3 in 2026: How It Compares to Eleven v4 and When to Use It
Oct 2026
Eleven v3 is the ElevenLabs model that brought audio tags and multi-speaker dialogue, and it is still in Flick's Text to Voice picker, next to its successor Eleven v4. It costs the same 8 credits a take. The question is when you would still choose it.
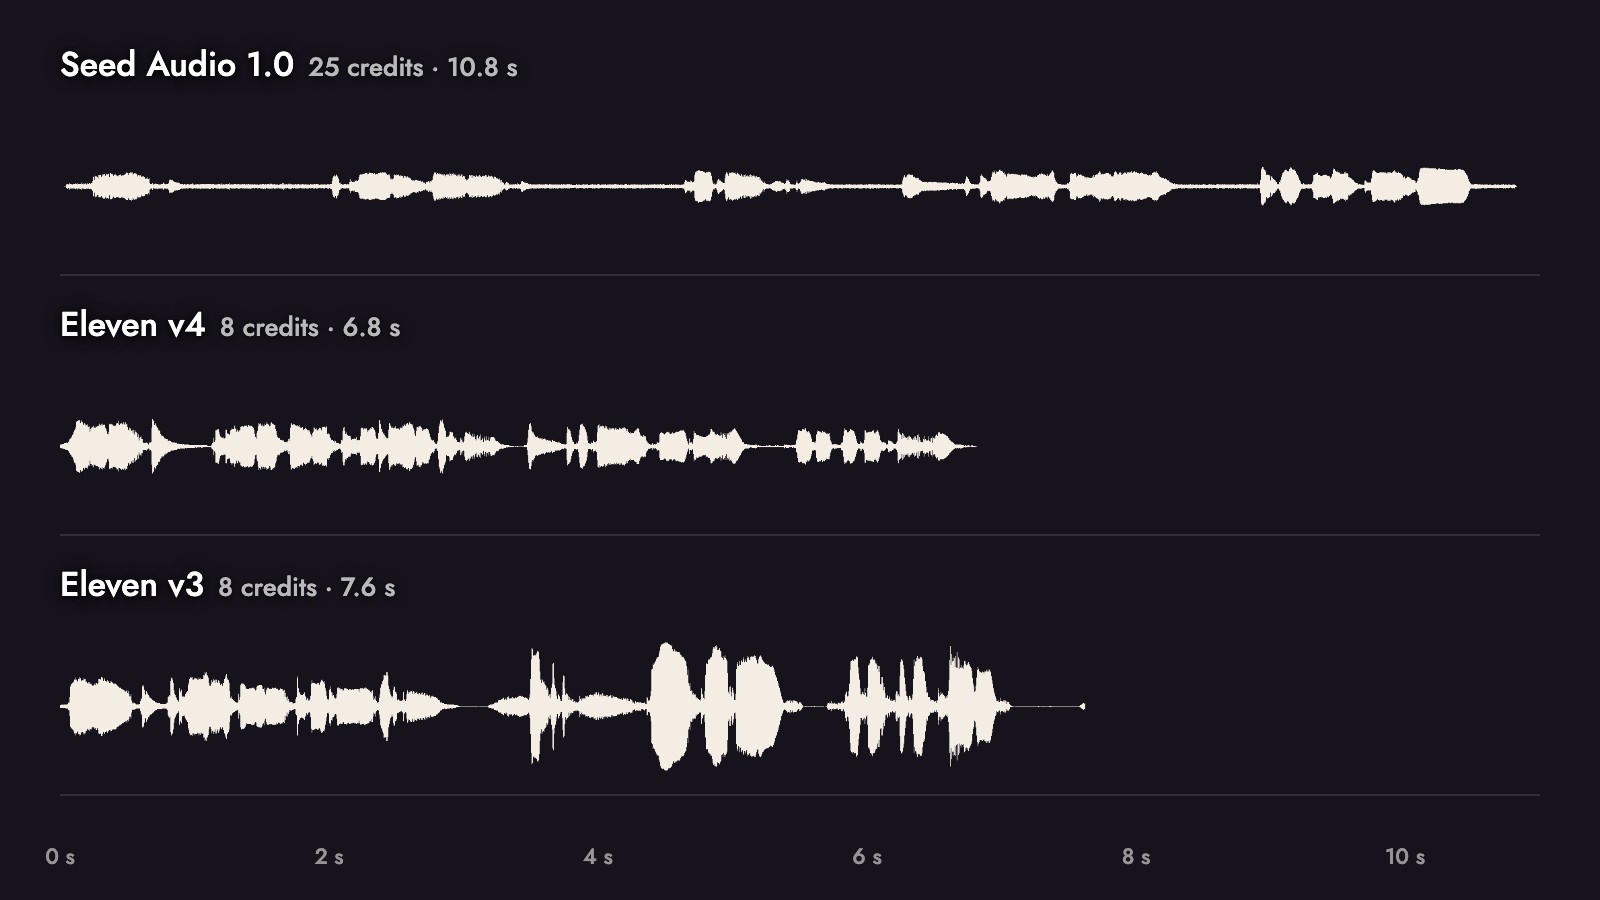
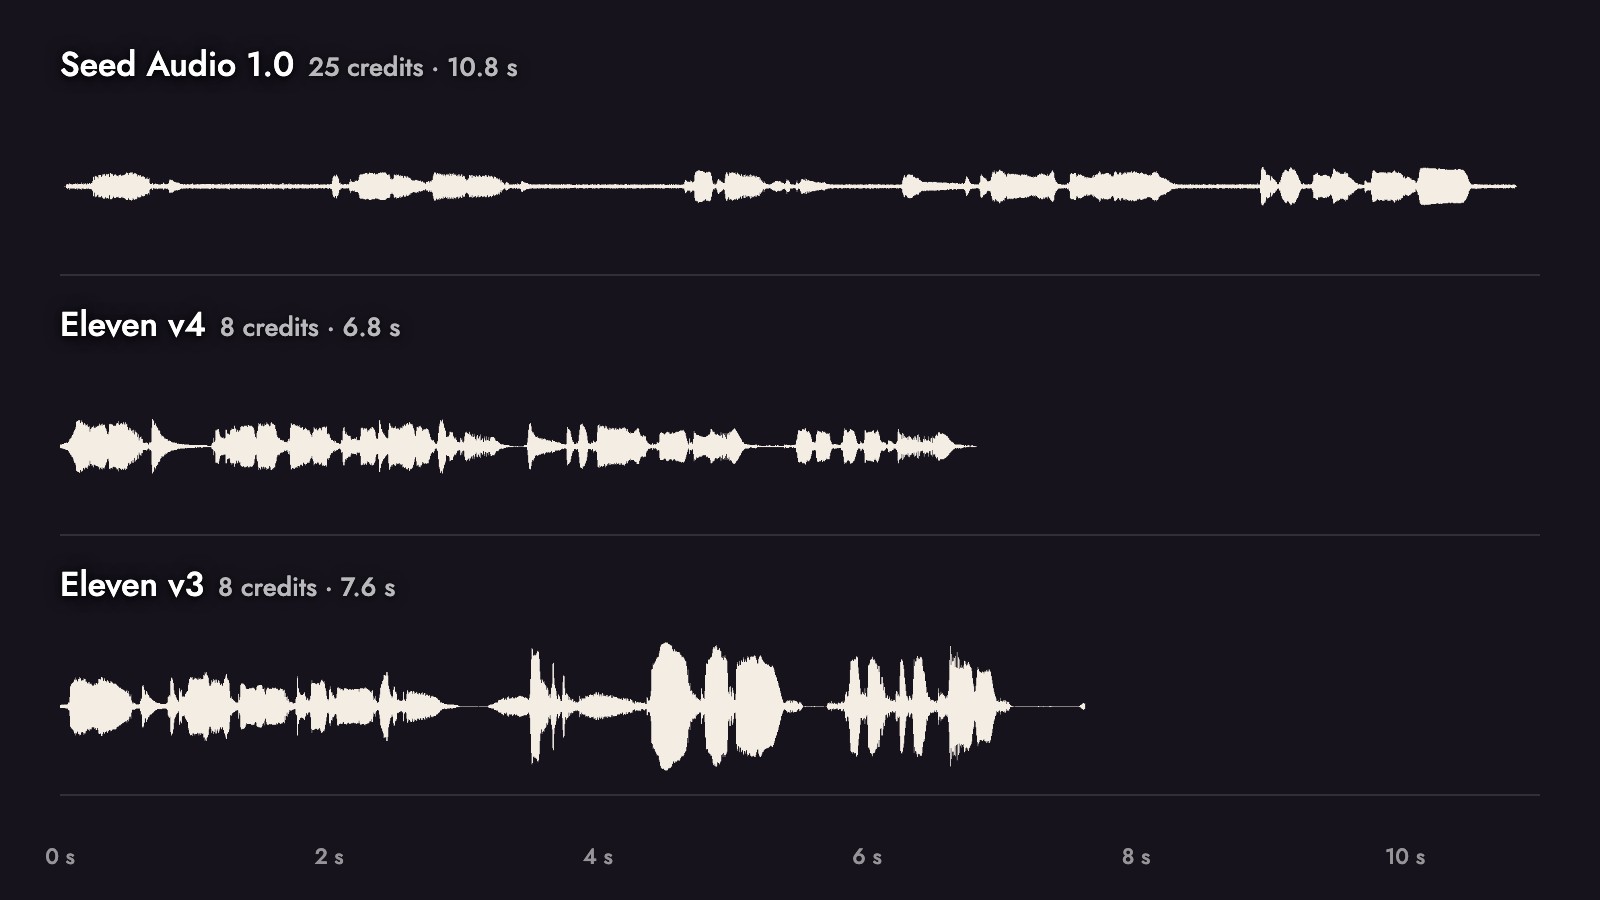
Short answer from our tests: mostly when you are matching clips you already made on v3. On the same lines it came third of three for emotion, ran much louder, and skipped a laugh tag that v4 performed.
Quick answer: should you use Eleven v3?
In the Text to Voice node, Eleven v3 is one click away in the model menu. Then:
- Default to Eleven v4 for new work. Same price, more expressive in our test, and ElevenLabs recommends it.
- Use v3 to match existing v3 takes. Same voices, same behaviour, so new lines sit with old ones.
- Level v3 takes before mixing. Our v3 dialogue measured -15.8 LUFS, about 12 dB louder than v4.
| Spec | Eleven v3 on Flick |
|---|---|
| Maker | ElevenLabs |
| Price on Flick | 8 credits per take, any length |
| Plans | Every plan, including Free |
| Speakers per take | Up to 10, one library voice each |
| Languages (ElevenLabs) | 70+ |
| Text per request (ElevenLabs) | 5,000 characters |
| Settings | Stability, 0 to 1 (default 0.5) |
| Output we got | MP3, 44.1 kHz mono |
| Our takes | 7.6 s and 7.7 s long; 139 s and 10 s to finish |
Voice your scene in Flick
Pick a voice per character and direct the delivery with tags.
Test 1: the two-person dialogue
The same two voices and lines we gave Eleven v4 and Seed Audio 1.0:
Every word came back as written. It ranked third of three for emotion in our listening, and it was by far the loudest file:
| Take | Loudness | Peak |
|---|---|---|
| Eleven v3 | -15.8 LUFS | -1.6 dBFS |
| Eleven v4 | -28.0 LUFS | -11.1 dBFS |
| Seed Audio 1.0 | -30.6 LUFS | -14.9 dBFS |
A peak of -1.6 dBFS leaves little headroom. If you cut v3 lines next to v4 or Seed Audio lines, bring them to the same level first.
Test 2: audio tags on v3
[whispers] Did you hear that? [short pause] Something is moving behind the gate. [nervous laugh] It's probably just the wind.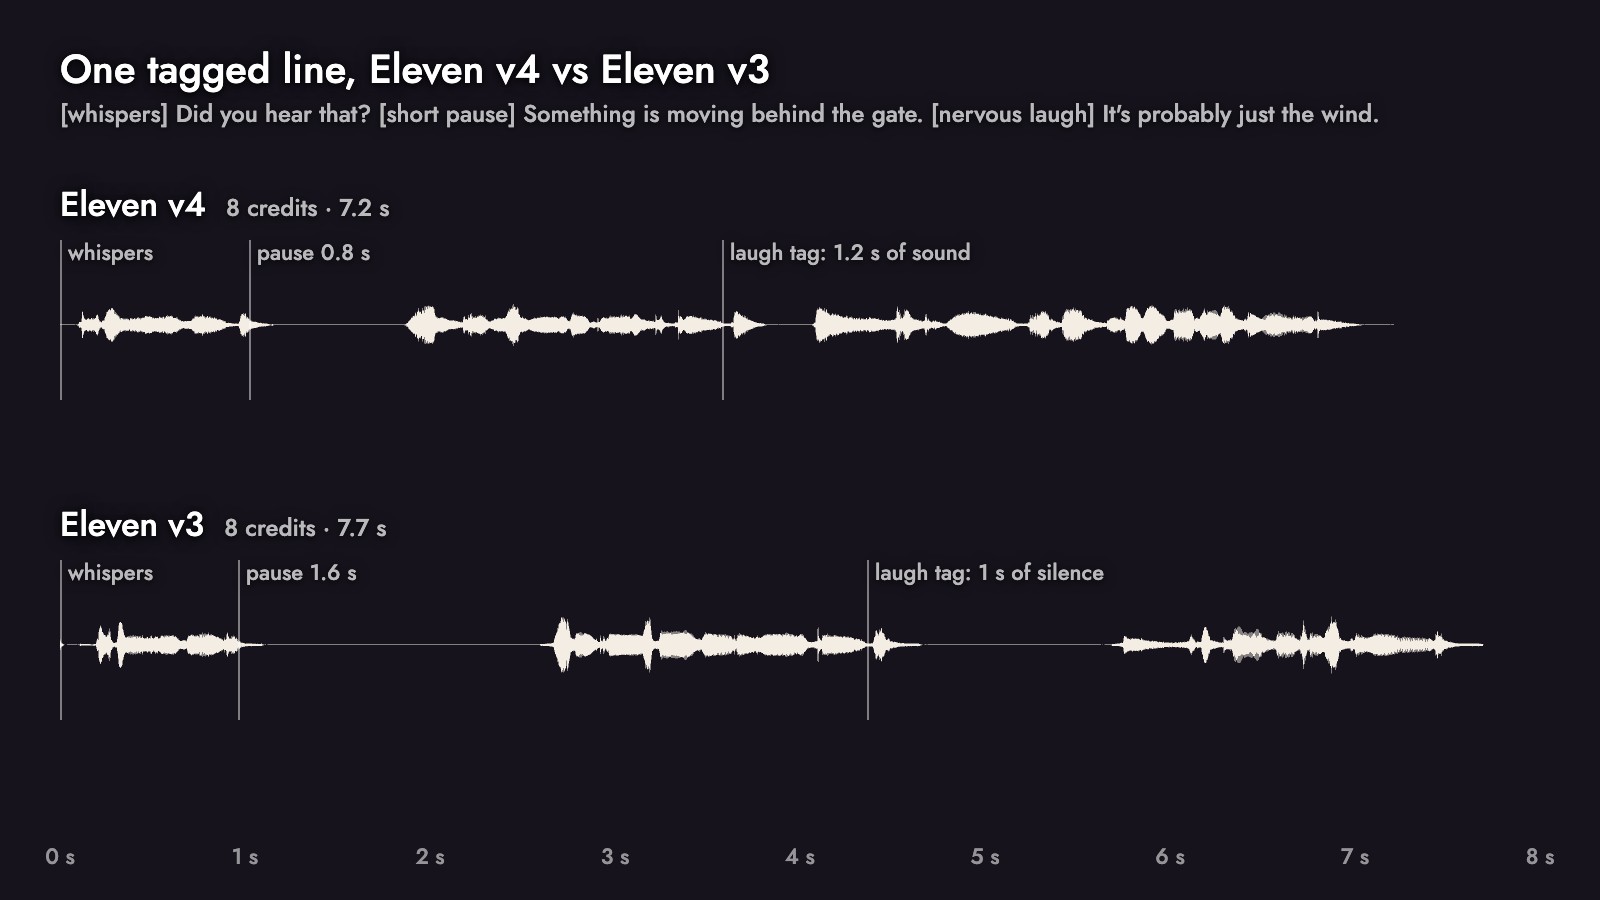
What we measured, against Eleven v4 on the same line:
| Tag | Eleven v3 | Eleven v4 |
|---|---|---|
| [whispers] | Judge by ear: level does not show a whisper | Judge by ear |
| [short pause] | 1.6 s | 0.8 s |
| [nervous laugh] | About 1 s of silence | About 1.2 s of sound |
Neither model read a tag aloud as a word. But v3 treated the laugh as a gap, and its "short" pause was twice v4's.
When Eleven v3 is still the right pick
- You are adding lines to a project voiced on v3. A new model can shift a voice's character; staying on v3 keeps new lines consistent with old ones. See voice consistency.
- You liked a specific v3 take. Regenerate on v3 rather than chasing the same read on v4.
For everything else, start on Eleven v4. ElevenLabs recommends v4 over v3, and notes that Professional Voice Clones are not fully optimized for v3.
Setting up Eleven v3
The panel is the same as Eleven v4's: pick the model, choose a voice per speaker with Select voice, type the lines, add speakers, and check the 8 on the Run button.
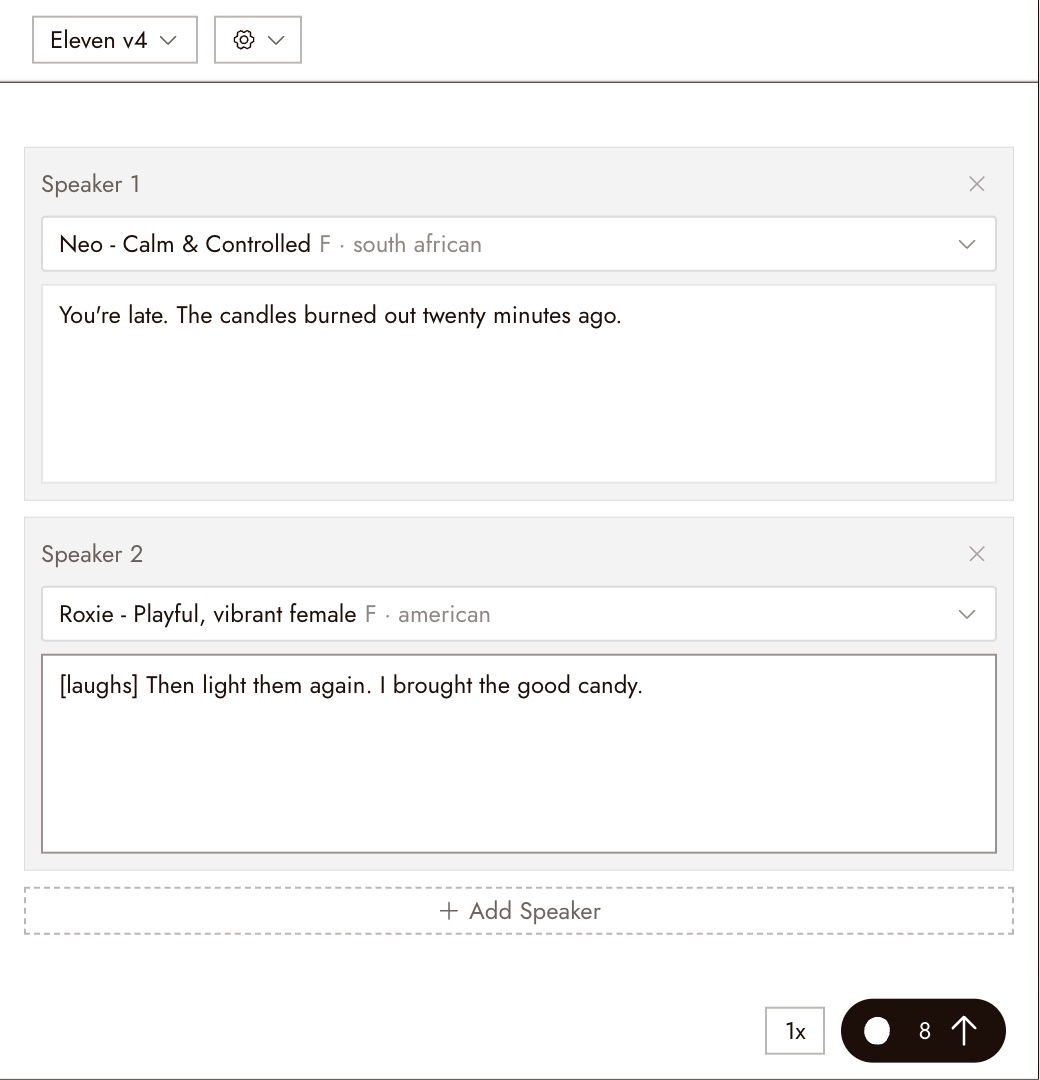
To move a take between models, use Regenerate on the finished audio: the new node keeps the speakers and lines, so you only switch the model.
What it costs and how long it takes
8 credits per take on every plan, the same as Eleven v4. Our two v3 runs took 139 seconds and 10 seconds: the same model, very different waits, so do not read much into one run. Rates for every model are on model credit costs.
Sources
- Models, ElevenLabs documentation, checked October 21, 2026
- Prompting Eleven v4 and v3, ElevenLabs documentation, checked October 21, 2026
- Tests, credit prices, timings and loudness measurements from a Flick canvas, October 2026
Guide correlate
- Text to Voice
- Voice consistency
- Character Dialogue
- Build the sound
- Model credit costs
- How to use Eleven v4
- Eleven v4 vs Eleven v3 vs Seed Audio 1.0
Domande frequenti
Is Eleven v3 still available on Flick?
Eleven v3 or Eleven v4? Eleven v4 for new work: same price, more expressive in our test, and it performed a laugh tag that v3 left silent. Use v3 to match earlier v3 takes.
Eleven v3 or Eleven v4?
Why are my Eleven v3 clips louder? Our v3 dialogue measured -15.8 LUFS against -28.0 on v4. Level them before mixing.
Why are my Eleven v3 clips louder?
Does Eleven v3 support audio tags? Yes. In our test it paused for [short pause] (1.6 seconds) but left [nervous laugh] as silence.
Does Eleven v3 support audio tags?
How many languages does Eleven v3 support? 70+, according to ElevenLabs, against 90+ for v4.